Want to join in? Respond to our weekly writing prompts, open to everyone.
Game Log | Ace Combat 8 - 001 🎮
from  Dad vs Videogames 🎮
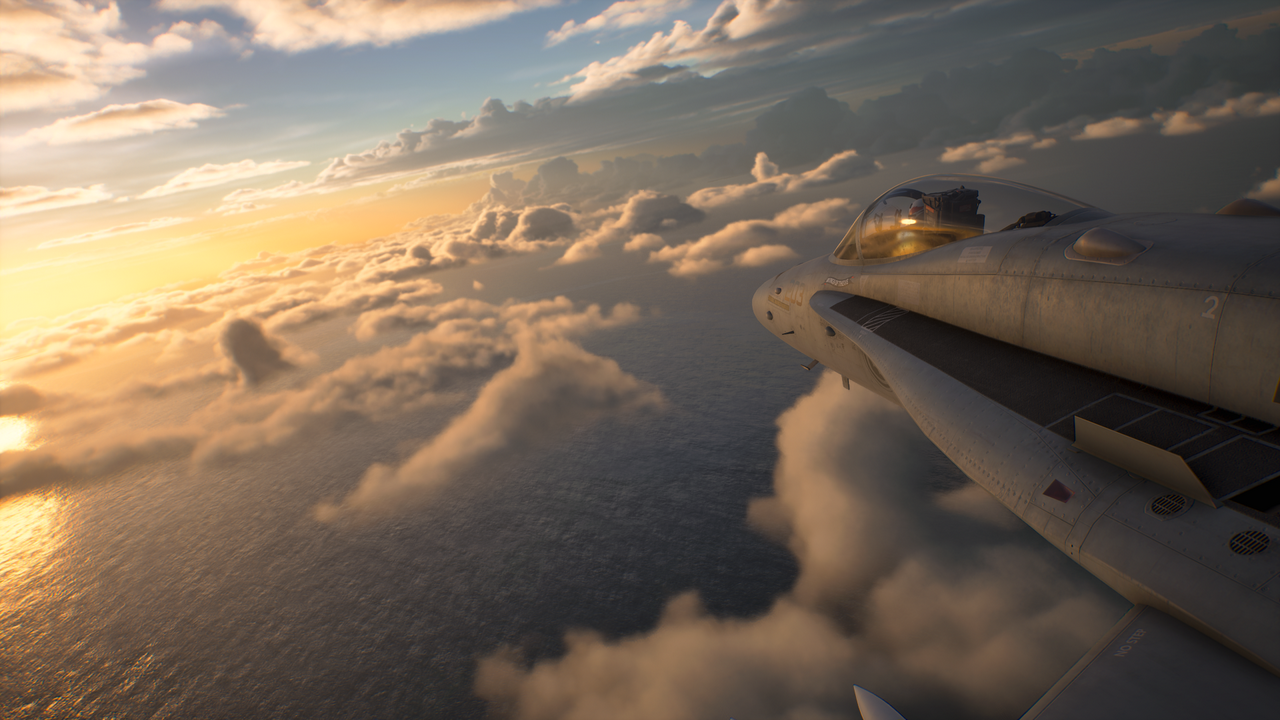
Finally got my hands on Ace Combat 8: Wings of Theve last week. Sharing my thoughts on the game before I lose track of time doing something else, like playing more Ace Combat 8.
First off, the opening cinematics are interactive, which is pretty cool. I don't remember playing a game with this feature. Granted, I don't play that many games. But still, this was cool.
The opening cinematics also have this sort of Metal Gear feel to them. I don't know why, but I like it. It gave me goosebumps when I went through it.
I like that this game brought back some focus on your wingmen, or fellow pilots. The chatter during flight brings the game to life in a good way. I do not like the “voice in your head” approach to telling your character's story, though. If they're going to let you respond to dialogue in the game, then they might as well let you be your own character instead of having somebody else's voice in your head.
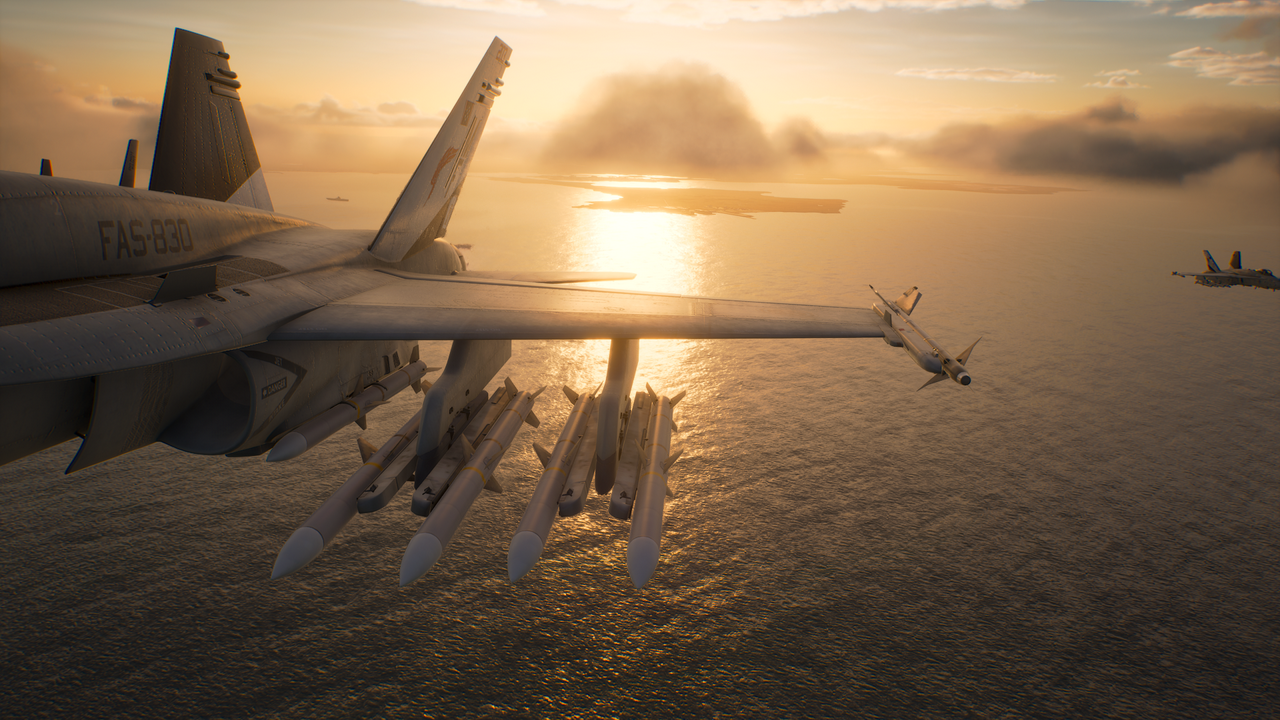
The graphics in the game are excellent, not just for the planes but for the character models as well. I can see why so many players are infatuated with Tasha.
I've played the first few missions, and the replay system and camera are much improved over Ace Combat 7. The replay camera includes some angles that make for great screenshots. And I already said the graphics are excellent, but my God, the planes in this game look really good!
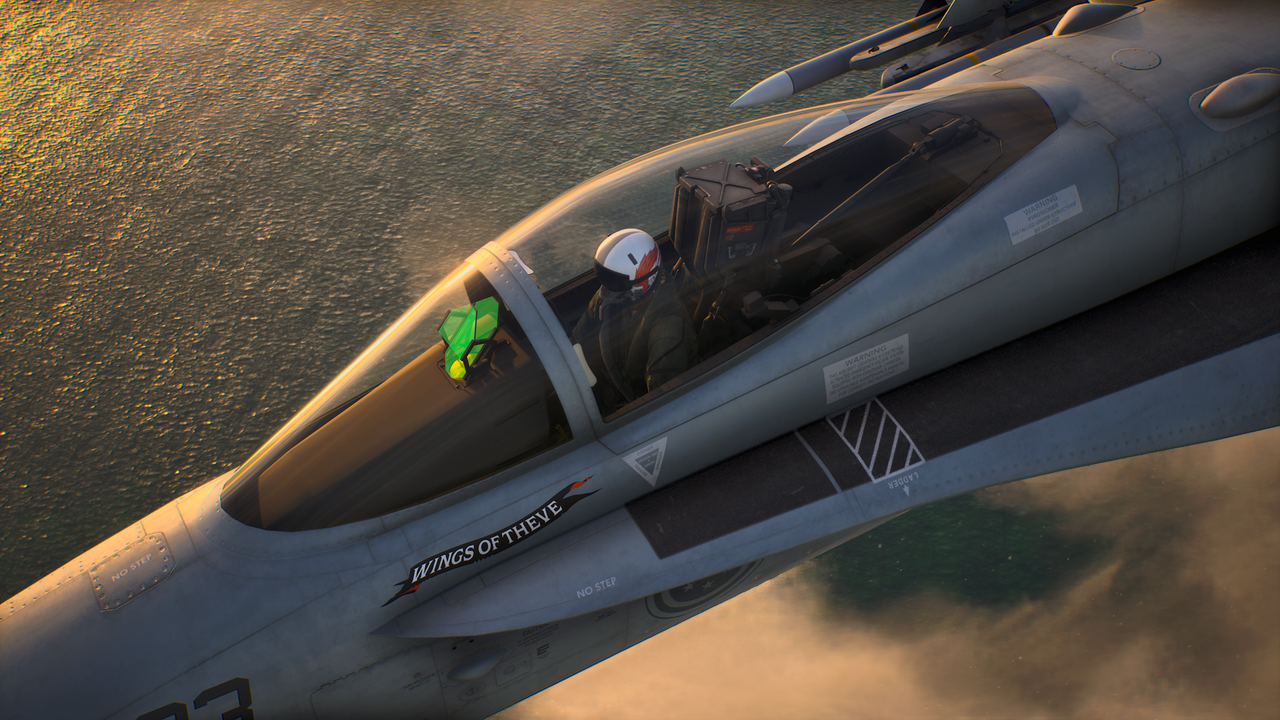
You start the game in an F/A-18C. It seems slow to respond to roll inputs. Either that, or they decreased the sensitivity of the analog stick. I feel like they tried to slow the game down a bit, making it a little more simulation and a little less arcade.
But who am I kidding? This is still very much an arcade game.
Sorry I'm jumping back and forth, but back to the story. I much prefer the player's story and companions in this game over those in Ace Combat 7. It might be too early to compare the two games, though, considering I've only completed a few missions.
I'll end this post with a compilation of clips from my first few hours with the game.
https://youtu.be/ywwmeDA0c5g?si=8QykhkiHtzl7CKvi
Tags: #GameLog #AceCombat8
No more crush
from An Open Letter
I spent the entire day with a today. We started around 11:20, and it is now 10:30 PM. I had fun, and I am happy with today, but I will say that I don’t think I’m interested in her anymore. There were several things that just made me less and less interested. I think the biggest one for sure was she mentioned that she had a dream about a guy that she talked to like two years ago, and so she asked him out next week. And this reminds me of I think the original reason why I kind of lost interest in Her. She had told me she was not really ready for a relationship, and while we were talking and flirting all that she kind of started flirting with someone else at something I invited her for. And I know that the number one thing that turns off a suitor is expressing interest into other people. But I also know that we have been friends for a while now and so she just might not be interested in me like that. But I think past that, there were a couple things that made me kind of feel like her caring about my birthday or me was more of an exception rather than the norm. She mentioned that she was happy. She got to do the stuff for my birthday because her brother doesn’t really celebrate his birthday either. And I kind of feel like in a way I was a proxy for him. And also, she didn’t notice that I had mentioned. I don’t like coconut a few times, as we apparently made a coconut cake. And it mostly just kind of felt like she wanted to bake for baking sake, rather than for me, which is not a bad thing, but just not necessarily a super strong indicator that she cares about me like that. But also we had talked about what we expect out of a relationship, or what we are looking for, and she couldn’t really articulate it well, but ended up, essentially saying that her demand was for the person to be chivalrous. And for her that meant things like opening her car door for her or giving her the princess treatment. And I felt like a bit of the ick from that, but we did talk about it a bit, and I think I kind of isolated my issue with that. I think that sort of stuff is putting an expectation on the man in the relationship, which is fine if there are other expectations put solely on the woman. And this mostly revolves around my belief that a relationship should fundamentally be equitable. Like skill based matchmaking. And when there are expectations like this, it feels like it is because the woman is performing her traditional, gender, roles, or expectations, but that is something that I don’t want in a relationship. I think all of the expectations that I have for a relationship are ones that they also have for me. And so if someone expects me to compensate in certain ways by being chivalrous, for example whether it’s financially, or in these small acts of services constantly, it feels bad to me because it feels like that will never be reciprocated. I can’t really think of anything that I would want my partner to do for me that I wouldn’t be doing for them. And I think that it just ends up feeling like a One Direction service towards this person. And I don’t think that’s what I look for in a relationship.
Minding the Midnight Hour
from AnOublietteofThought
When did having a life worth inhabiting become so unfamiliar and strangely defined. The eagerness for popularity people have crushes me. I suppose it always has as I've never really understood it at all. The very idea of what should and shouldn't receive recognition confounds and saddens me.
I'm not really sure where my thoughts are, atm. A bit scrambled for sure. The priorities of our civilization consistently disappoint me. I keep fighting against shutting down, but there are moments where it's more challenging than others. This appears to be one of them.
How strange it is to both be at a loss but content in who you are simultaneously. I've been told aplenty that I'm either too unfocused or far too focused. I think, perhaps, the reality is that I'm simply not focused on what others wish I was. I think I am beginning to accept that I never will be.
© 2026 AnOublietteofThought. All rights reserved.
Private photos on iPhone, explained plainly
from ArkWarden Guides
Seven short guides on hiding, locking and deleting photos and files on iPhone, and what each option really protects.
I. Hide and find
01 How to hide, unhide and find hidden photos on iPhone Hide a photo, bring it back, find the Hidden album, and learn what hiding does not protect.
02 Do hidden photos sync to iCloud? When hidden photos reach iCloud, who can see them there, and how to stop it.
II. Lock and delete
03 How to lock photos on iPhone Lock the Photos app with Face ID on iOS 18 and later, including iOS 27, and see who can still open it.
04 How to lock a folder on iPhone iPhone cannot put a password on one folder, so here are the options that do work.
05 How to permanently delete photos on iPhone Why deleted photos stay for 30 days, and how to remove them so nobody can recover them.
III. Choose a vault app
06 7 best photo vault apps for iPhone Seven vault apps tested side by side on how they encrypt your files and how you get them back.
07 The best apps to hide photos on iPhone From Apple's Hidden album to dedicated vaults, what each type of app really protects.
Hiding a photo is not the same as protecting it.
ArkWarden keeps your photos and files in an encrypted vault on your iPhone.
Private Fotos auf dem iPhone, einfach erklärt
from ArkWarden Guides
Sieben kurze Anleitungen zum Ausblenden, Sperren und Löschen von Fotos und Dateien auf dem iPhone, und dazu, was jede Option wirklich schützt.
I. Ausblenden und finden
01 Fotos auf dem iPhone ausblenden, einblenden und finden Ein Foto ausblenden, wieder einblenden, das Album „Ausgeblendet“ finden und sehen, was Ausblenden nicht schützt.
02 Werden ausgeblendete Fotos mit iCloud synchronisiert? Wann ausgeblendete Fotos in iCloud landen, wer sie dort sehen kann und wie du das stoppst.
II. Sperren und löschen
03 So sperrst du Fotos auf dem iPhone Sperre die Fotos-App mit Face ID ab iOS 18, auch unter iOS 27, und sieh, wer sie trotzdem öffnen kann.
04 So sperrst du einen Ordner auf dem iPhone Das iPhone kann keinen einzelnen Ordner mit Passwort schützen, aber diese Optionen funktionieren.
05 So löschst du Fotos auf dem iPhone endgültig Warum gelöschte Fotos 30 Tage bleiben und wie du sie entfernst, damit niemand sie wiederherstellen kann.
III. Tresor-App wählen
06 Die 7 besten Foto-Tresor-Apps für das iPhone Sieben Tresor-Apps im direkten Vergleich: wie sie deine Dateien verschlüsseln und wie du sie zurückbekommst.
07 Die besten Apps zum Verstecken von Fotos auf dem iPhone Vom Album „Ausgeblendet“ von Apple bis zu spezialisierten Tresor-Apps: was jede Art von App wirklich schützt.
Ein Foto zu verstecken ist nicht dasselbe wie es zu schützen.
ArkWarden speichert deine Fotos und Dateien in einem verschlüsselten Tresor auf deinem iPhone.
arkwarden.app · Alle Anleitungen
Fotos privadas en el iPhone, explicadas sin rodeos
from ArkWarden Guides
Siete guías breves sobre cómo ocultar, bloquear y eliminar fotos y archivos en el iPhone, y qué protege de verdad cada opción.
I. Ocultar y encontrar
01 Cómo ocultar, mostrar y encontrar fotos ocultas en el iPhone Oculta una foto, recupérala, encuentra el álbum Oculto y descubre lo que ocultar no protege.
02 ¿Las fotos ocultas se sincronizan con iCloud? Cuándo llegan las fotos ocultas a iCloud, quién puede verlas allí y cómo evitarlo.
II. Bloquear y eliminar
03 Cómo bloquear fotos en el iPhone Bloquea la app Fotos con Face ID en iOS 18 o posterior, incluido iOS 27, y descubre quién puede abrirla igualmente.
04 Cómo bloquear una carpeta en el iPhone El iPhone no permite poner contraseña a una sola carpeta, así que aquí tienes las opciones que sí funcionan.
05 Cómo eliminar fotos definitivamente en el iPhone Por qué las fotos eliminadas se quedan 30 días y cómo borrarlas para que nadie pueda recuperarlas.
III. Elegir una app de bóveda
06 Las 7 mejores apps de bóveda de fotos para iPhone Siete apps de bóveda probadas una junto a otra: cómo cifran tus archivos y cómo los recuperas.
07 Las mejores apps para ocultar fotos en iPhone Desde el álbum Oculto de Apple hasta las apps de bóveda dedicadas, qué protege de verdad cada tipo de app.
Ocultar una foto no es lo mismo que protegerla.
ArkWarden guarda tus fotos y archivos en una bóveda cifrada en tu iPhone.
arkwarden.app · Todas las guías
from  Brand New Shield
This is a hypothetical setup for the Brand New Shield. What would the league look like? What markets would be looked at? How would the ownership model work? Let's dive in.
I truly believe dominating the indoor game is the way to go here. The indoor game from a prominence standpoint has lost its way and is filled with a combination of fledgling and fly-by-night minor leagues. There isn't an exact number of teams in mind but it would have to be a number where a good schedule would make sense. A hypothetical situation would be a 12 team league split into two conferences and every team in the regular season would play every team in their conference twice. So, 12 team league with a 10 game regular season would work here. Conference winners would then face each other in a title game. In this scenario there'd be an 11 week season and every team has a week 6 bye. The universal week 6 bye would be a great opportunity to do mid-season fan fests and other activities to engage the communities the teams are located in. There could even be broadcasts from these fan fests with player and coach interviews and Q&As to make it a more interactive experience that could be broadcast through an official league app. You'd then have the championship game 2 weeks after the end of the regular season to give the teams an extra week to prepare.
The markets these teams would be located in is something that I have gone back and forth on. The easy way out is just to use major markets but in terms of being the major league for everybody else, that doesn't fit the vibe. It would be about researching great markets with great fan bases that get overlooked. Giving what people consider minor league markets their own major league team is personally what I'd rather do and I believe there is a way to make that work if this does ever get off the ground. I'd prefer places with a proper arena already in place to lower the initial infrastructure investment and focus more resources in other areas.
As far as the ownership model goes... A single ownership model is the way to go so that all things are created equal. However, a way to distribute Green Bay Packers or Saskatchewan Roughriders style shares of the teams that include some perks for the fans who purchase them is also something I would definitely consider.
There is a long way to go before this vision could ever come into fruition. Thank you all for reading this, I really do appreciate it.
from James
Small Changes That Make Your Beauty Routine Easier
A beauty routine should fit comfortably into your day. If getting ready means searching through crowded drawers or trying products you rarely enjoy using, a few thoughtful changes can make the process simpler.
Start with what already works. Keep your favorite everyday products together so they are easy to find. Separate occasional makeup, styling tools, and special-event accessories from the items you reach for each morning. You can enjoy variety without keeping everything on the counter.
Choose Inspiration That Suits Your Habits
A haircut might look beautiful in a photograph, but consider how you would wear it at home. Before your next salon appointment, think about whether you usually air-dry your hair, use styling tools, or need enough length to tie it back. Discuss those details with your stylist alongside your reference pictures.
The same approach works for nails and makeup. You might love the color of an elaborate manicure while preferring shorter nails and a simpler finish. Borrow the detail you like and adapt it to your preferences.
For more ideas, The Serenity Lab covers hair, makeup, nails, and everyday self-care topics that can help you explore different looks.
Buy With a Clear Purpose
Before purchasing something new, decide what you want it to do. Are you replacing a favorite product, trying a shade you genuinely like, or buying something similar to several items you already own?
A short wish list gives you time to consider each purchase. Check the product details, compare your options, and picture when you would actually use it.
Keep an Everyday Version
Leave room for busy mornings. A familiar hairstyle, a few preferred makeup products, and accessible tools can give you a dependable starting point. Save longer experiments for days when you have time to enjoy them.
The goal is a routine you feel comfortable repeating, with enough flexibility to try something different whenever you want.
Day 150
from Out of Office
Well, the feel-good show I ended up binge watching (and have already restarted) has brought my love life back up to my attention. I feel so ready and energized to meet and connect with someone, but I have no idea where to start.
It seems silly to start thinking about this now since I am about to move, but I almost wish I had someone to share this excitement with outside of my family. I know Colorado will bring new opportunities in all areas of my life, but I can’t help but wonder if the man I am manifesting even exists. I can’t be asking for too much, right? I mean I see this type of man portrayed in movies and shows, within my family and friends, and even strangers on the internet. I know some of them are real, but is there one for me?
That last sentence sounds a little hopeless… I mean duh, yes, obviously there is someone for me. And I know I will never settle for less than I deserve, so I continue to practice patience and focus on different parts of my life – career, home, friendships… I know it is a matter of ‘when’ and not ‘if’, so I will hold on to that for now.
Thank you for your message. I am currently out of office — but will return at the end of the month.
Day 149
from Out of Office
Today was nowhere near as productive as yesterday, but I made some continued progress. It was a cold and gloomy day so getting cozy and watching a feel good show felt more aligned with the type of day than yesterday.
I did manage to get myself ready on time(ish) for therapy and then I went to go meet with an old work friend. We caught up for the first time since I left my job and filled each other in on the wild rollercoaster the last few months have been. I broke the news of the move to her and she seemed very surprised, but excited for me.
I can’t pinpoint exactly how this move is making me feel, but it feels like I am on the cusp of a major realization or life change. I think it will be really good for me to get out of my bubble and try something entirely different.
Thank you for your message. I am currently out of office — but will return at the end of the month.
Day 148
from Out of Office
The decluttering challenge has begun.
It is absolutely crazy how much junk we accumulate without even realizing it. I decided it is best to work on decluttering some boxes and things I have stored before I start to pack, and it has been a wild ride. I think most of it is trash, but I get so sentimental about memories that it is really hard to know what to get rid of.
I tend to hold on more to cards, notes, letters, notices, and receipts more than other physical items. I love looking back and seeing thank you or birthday cards from people I have lost touch with, or finding an old receipt and remembering that trip or seeing how much the economy has changed.
I have made some slight progress, but I did not get anywhere near finished and now I have a heap of junk on my bed. I hope I can find the motivation to continue getting rid of things in the coming days so I can clear my mind and focus on packing next.
Thank you for your message. I am currently out of office — but will return at the end of the month.
Day 147
from Out of Office
What an incredible day. I felt like I was on cloud 9,000.
A wave of optimism hit me strong today. I can’t believe we are making it. I can’t believe the changes around the world, the changes coming to my life. It has been a hard journey, and now I feel more hopeful than I ever had before. I feel so ready for this next step. I trust and believe everything is working out exactly as it should. I am believing in the process.
I spent hours at the pottery studio today. It felt incredible to get so much done. I wanted to go for a run too, but it didn’t work out with my schedule. Maybe someday soon I can restart the running I feel like I am starting to lose. I do also have a lot to do before the move so my schedule is actually pretty tight.
Thank you for your message. I am currently out of office — but will return at the end of the month.
from Blog of Sand
Inbetweeners 45- Zane
So by the time the players had finished the Xalatra questline, they had encountered the NPC Zane only once. They didn't even remember who he was, but boy did he remember them. Zane's official title is “Special Operator” for Mechanus. This is a catch all term for a third party contractor who does work for Mechanus. They farm out work to countless such operators and contractors, but Zane is the one they send in for the most difficult jobs that require the most moral... flexibility.
I took my inspiration for Zane from the character Conrad Kellogg in Fallout 4, in particular that he is a mercenary who trades work for cybernetic upgrades and extended lifespan and has no moral compunctions about dirty work. I've posted his statblock previously, but he is a CR 23 with numerous cybernetic offensive abilities and buffs. I even made a direct reference to Fallout with his “VATS” ability that lets him make 7 full attacks with his gun arm once per short rest.
Zane has been a contractor for Mechanus for a long, long time. He has no particular allegiance to the gearheads, as he calls them, but they simply pay the best and provide a steady stream of high profile jobs. As he became more powerful, his rate and abilities exceeded most mercenary work. He was beneath guarding emperors, taking out enemy warlords, or even hunting down massive dragons. For him, only big game would do, and nothing is bigger than existential threats to reality itself.
When the Protectors of the Weave finally got a handle on where the players were and the network of rooms, they brought Zane into the fold to plan their ambush. They would assault the Grey Room directly, but wanted Zane has back up to clear up any who escaped. Zane carefully studied the map of the rooms that had been put together by the Protectors documenting various sightings and Far Realm energy. He figured the players would go to the market if they escaped, and that the Protectors would try to corner them there. Most other paths led to more peril, so they would probably try to cut through the Throne Room. Mechanus showed that the Throne Room took them to some sort of storage area, and beyond that the path disappeared. There was a gap of time between when the players went through the Throne Room and returned that took a couple of weeks, so Zane correctly deduced that was their emergency escape route. He meticulously planned an ambush that they would not be able to beat.
The “door” in was the main doors to the great Throne Room hall, and the “door” they needed to go through was on the other side of the Throne. There was another “door” they found off to the right of the throne, and Zane would put himself directly there, dropping down walls of force to block the other two. He knew the targets were unpredictable, and that despite their appearance as a mere mid tier adventuring party were exceedingly dangerous. Intel picked up that they had taken out an entire group of vampires, a small army and made inroads with the church of Torm by fighting off an infernal incursion. Rather than face them immediately, he wanted to see what tricks they had up their sleeve. So his plan was to deploy a “corrected” demon, a special project he'd been working on in tandem with Mechanus since they had occupied The Torment, where demons were captured, and surgically enhanced to remove their free will and turn them into terrifying weapons. The project was controversial, and there was a lot of red tape around field testing. All red tape had been lifted for this particular capture, so he figured why not use one of them. By all accounts a single corrected demon should make short work of a mid tier adventuring party. Its subjugation pulse alone would stun them, and the corrected demon's martial ability was more than enough to take them head on. If they somehow defeated it, he had several more on standby to be teleported in.
It reminds me now I'm not sure how much I established of Zane's presence in the Torment. Since Uzo used a temporal duplicate when fighting the Warden, the reality distortion was like a flare signal sent out to Mechanus. They came to investigate soon after. With how dangerous the Torment was known to be, and its remote location in Hades, they sent Zane first. He quickly saw the potential in the prison which had fallen into chaos, and spearheaded the project to start to use it to make the corrected demons, building it on the work of the Jailer and the Warden. Mechanus signed off, reluctantly, as it was connected to their attempt to locate and neutralize the Interloper. So prior to this encounter in the Throne Room, that's where Zane had mainly been “operating.”
Anyway, the corrected demons were merely an appetizer. There to soften up the targets and deplete some of their spells and resources. The main event was Zane, and two Maruts assigned to him for this job. It was exceedingly rare for Maruts to be deployed under the command of a third party contractor. They were the prized constructs in Mechanus's arsenal, the absolute enforcers of law. However, with how dangerous the targets were, Mechanus made an exception. Zane knew though that the Maruts were there to watch over him as much as they were the players. Mechanus could not afford any mistakes. So, in addition to the corrected demons, Zane plus two CR 25 constructs were waiting. A Marut alone is strong enough to level a top tier adventuring party, and two plus Zane would be overwhelming for any of them. Hell, Zane figured that with the trap he set up they could probably take down the Resplendent Six, the premier heroes of the multiverse. The overkill was the point. It was made clear to him that under no circumstances could the players be allowed to escape. Use of overwhelming force, pushing the probability of success asymptotically towards 100% was the instruction. So, that is what he would do. There should be no way it could fail. Even if the players managed to summon an ancient red dragon infested with a Far Realm parasite, he had enough power to take it down. Yet somehow, the players sabotaged everything.
When they came through, the goblin ranger somehow took down Zane's corrected demon with a single volley of arrows. Something wasn't right... the way his bow warped reality around it. The damage was... unnatural. Clearly these were the targets the Protectors sought to bring down. Zane dispensed with the idea of deploying more of the Corrected Demons from the Torment after such a pitiful display. Zane was very disappointed and would need to troubleshoot that for later. For now, these players were clearly too dangerous to keep around. His plan from here was simple. The Maruts and he would kill them in under 12 seconds, bring their souls and bodies back from Mechanus, revive them in stasis containers, and then the Protectors would take it from there and he'd get paid. Handsomely.
However, before Zane could act, judgement arrived. The Judgement of Torm. The renegade angel Lurian, who had come up briefly in the strategic meetings, stormed through the door behind Zane. They knew from the prison records in the Torment that Lurian had been imprisoned and was freed by the targets. Soon after, he was seen taking over the Shadow of Torm, and rebranding it and greatly swelling its ranks in what could only be called a militant-theocratic-populist uprising. Mechanus was monitoring that situation closely and evaluating its relation to the players. Zane had apparently discovered just how connected the events were.
No matter, Zane would kill the angel, his followers, and the players. That is why he brought overwhelming military power, to neutralize any threats or impediments to the mission. His instructions were explicit, take the targets at all cost, and neutralize anyone who gets in the way. Once classified as existential threats, most of the rules of war were lifted. This is why Zane liked working the most dangerous contracts for Mechanus—hunting the reality breakers. His hands were unbound. He even had a moment of excitement. When else would he have the opportunity to kill an angel and have it be retroactively sanctioned? He'd fought many, many foes before. Defeated them all. But never an angel. Unfortunately Lurian did not come unarmed. He came armed with the most dangerous weapon of all... the law.
As soon as Lurian started reading the proclamation, Zane knew he was done. Despite being an existential threat, there were certain rules that had to be followed as part of balancing the powers between planes. He challenged the jurisdiction of the current operation and the case was airtight enough that the Maruts retreated. There goes his firepower. His ability to warp in more corrected demons along with it. Mechanus had pulled the plug. Since he was a third party contractor, Zane could still act against them. He liked his odds against the targets. He liked his odds against the angel and his possie. He didn't like his odds against them all together. He ran some instant heuristic algorithms to play out the different probabilities. Too many unknowns. The angel had single handedly taken out a top general of Mammon. The players powers were unknown variables, not bound to the weave. Novel powers never seen before. Maybe he could take them, but he didn't even know the risk. Zane had to retreat in humiliation. He had been outplayed.
By the time the proper paperwork was filed and jurisdiction was established, the players were gone. Going after Lurian would mean declaring war on Torm, Tyr, Bahamut, Pelor, and who knows how many more gods. And it didn't matter, the players went to the one place Mechanus could not reach them, the one place they had no jurisdiction and no real power—Sigil. Soon after Zane learned the players defeated Arkanos the Undefeated in the arena, an impossible feat. Two Maruts had definitely been the right call.
Mechanus and the Protectors of the Weave changed the mission. They had the Interloper quarantined. The players had the equivalent of diplomatic immunity in Sigil. No one would cross the Lady of Pain. So instead, they sought to treat with the players. Zane's contract remained largely intact. If the players left Sigil, he could capture them for the same rate. No planned ambush in coordination with Mechanus, but he could call in reinforcements if Zane had a line on them. To the Protectors it was a pivot, to Zane it was a retreat.
Going after them in Sigil was a non-starter. The Lady could erase him from existence with a thought. Even if she didn't take notice, the players had just defeated the most powerful gladiator in the mulitiverse and become celebrities. He needed to draw them into a more favorable environment. And more importantly, he needed allies who didn't abide by jurisdiction and weren't afraid to get their hands dirty. The players became Zane's obsession, and they barely knew he existed. He made the Torment his base of operations, and sought out a powerful ally to help him. Fortunately, it wasn't hard. Lurian was freed by the players and executed Mammon's top general. And the players defeated Arkanos and lifted Mammon's curse, taking out his biggest money maker. Zane reached out, and Mammon listened.
Zane had done work for Mammon before, but didn't like how stingy he was with pay. Despite being the wealthiest being in the multiverse, he was loathe to pay out and would find any reason to reneg. This was different though, he didn't care about the money. The players humiliation had become personal. So, a link was established between Minauros and the Torment, and they plotted...
When AI Should Not Explain Itself: Designing for Calibrated Trust
from  SmarterArticles
Sixteen point two per cent. That is how often people in one 2026 experiment caught a machine's mistake once it had explained itself in fluent, confident prose. Swap the explanation for a bare number, the model's own estimate of how likely its answer was to be right, and the rate more than doubled, to 37.5 per cent.
The figures come from controlled studies by Ruth Cohen and Sarit Kraus of Bar-Ilan University, Lu Feng of the University of Virginia and Ayala Bloch of Ariel University, posted to arXiv as paper 2604.03237. The first version had a title built for the conference circuit: “The Persuasion Paradox: When LLM Explanations Fail to Improve Human-AI Team Performance”. Its abstract did not hedge: “We identify a Persuasion Paradox: fluent explanations systematically increase user confidence and reliance on AI”. The authors argued that interfaces should put calibrated reliance and recovery from errors ahead of persuasive fluency.
Then something unusual happened. On 18 August 2026 the authors posted a revision with a new title, “Supporting Calibrated Reliance in Human-AI Collaboration: Different Strategies for Different Tasks”. The word “persuasion” has vanished from the text. The 16.2 and 37.5 per cent figures remain, but the revised statistics report that differences in error recovery across the four support conditions did not reach significance (p = .055). The new abstract closes on a far less quotable line: “no single support strategy is universally effective.”
Hold both versions in your head, because between them they contain the whole argument. The first is the story everyone wants to tell: explanations are a trap, and the explainable AI movement has been building persuasion machines. The second is the story the evidence supports: explanations reliably raise confidence, do not reliably raise accuracy, and help or hurt depending on whether the reader can check what they say. A paper about the dangers of persuasive fluency was, in its first draft, a little too persuasive. Its authors noticed and pulled it back. That is calibration in action, and it is exactly the behaviour designers should be trying to produce in everyone else.
So the useful question is not whether explanations are good or bad. It is narrower and harder. When should a system withhold its explanation, or restructure it? And what would an interface look like if its job were not to help people understand the AI, but to help them know when to ignore it?
Sixteen Per Cent and a Change of Title
Cohen and colleagues ran three experiments with participants recruited through university mailing lists, mostly people with STEM backgrounds, who were paid a bonus for each correct answer. Two tasks carried the weight: RAVEN matrices, abstract visual puzzles in which you choose the shape that completes a pattern, and logical reasoning questions from the LSAT, the American law school admission test.
The cleverest design was the multi-stage reveal. Twenty-seven participants answered each RAVEN puzzle three times: first alone, then after seeing the AI's predicted answer, then after reading an explanation, either a written rationale from a large language model or a heatmap showing which parts of the image the model weighted. Alone, they were right 37.0 per cent of the time. With the AI's answer, 49.8 per cent. With the explanation on top, 48.8 per cent. The explanation bought nothing in accuracy.
It did buy something else. In the paper's words, “confidence remained largely unchanged after the prediction stage and increased only after explanations were presented”. The prediction made people more accurate without making them feel surer. The explanation made them feel surer without making them more accurate. If you wanted one result to sum up the worry about fluent AI, that is it.
The between-subjects RAVEN study, with 100 participants across five conditions, is where the famous numbers live. Every form of AI support beat working alone by a wide margin: unaided participants managed 24.6 per cent, while the four AI-assisted groups landed between 53.5 and 60.5 per cent, with predicted probabilities at the top. On overall accuracy, though, the AI-supported conditions were statistically indistinguishable. The difference appeared in how people handled the AI's mistakes. “LLM explanations showed the lowest recovery rate (16.2%) despite high agreement (84.2%),” the authors write. The probability condition showed the highest recovery, 37.5 per cent, with 75.8 per cent agreement on correct predictions.
Read those pairs together. The explanation group agreed with the AI more when it was right (a gap that, like the recovery gap, fell short of significance) and caught it less when it was wrong. That is the signature of reliance that has stopped discriminating: trust that rises evenly across good and bad advice instead of tracking which is which.
The caveats matter, and the revised paper is admirably blunt about them. There was no power analysis in advance, and twenty people per condition is a small sample. The RAVEN probabilities were raw, uncalibrated softmax outputs. A “selective automation” strategy, in which the AI decides confident cases and hands uncertain ones to the human, is now presented only as a benchmark derived after the fact from the probability group's data. The pattern is consistent and striking. It is not yet proof.
The Same Explanation Wins at Logic
The LSAT study rarely makes it into social media summaries, and it is the part that turns a scare story into a design problem.
Eighty participants worked through ten LSAT questions with help from an AI whose answers were right 60 per cent of the time. One group saw only the AI's answer, one saw the answer plus a stated probability, one saw an expert-written explanation adapted from earlier research, and one saw an explanation generated by a large language model.
The language model's explanation won outright. That group reached 72.5 per cent accuracy, against 55.5 per cent for expert explanations, 48.5 per cent for the bare prediction and 47.0 per cent for probabilities. It was the only group to beat the AI's own 60 per cent, and it recovered best from errors, at 47.5 per cent against 35.0 per cent for probabilities. It even beat the human experts' explanations, which rules out the comforting idea that machine prose is simply worse prose. Here the fluent explanation was not a sedative. It was a tool.
Why would the same kind of support hurt in one task and help in another? The authors are careful not to overclaim, noting that task, model and explanation style all changed between studies. But the contrast lines up with an idea that runs through the field. An LSAT explanation lives in the same medium as the problem. If a model says an argument assumes that correlation implies causation, you can reread the passage and see whether it does. The explanation offers a claim the reader can test against evidence already in front of them.
A verbal rationale for a visual puzzle is different. It translates a pattern into words, and the reader has to translate it back. That is laborious, so most people do not bother. They register that the paragraph sounds like reasoning and move on. The explanation becomes a vibe rather than an argument.
In 2023, Helena Vasconcelos and colleagues at Stanford University and the University of Washington, including Michael Bernstein, Tobias Gerstenberg and Ranjay Krishna, gave this intuition a formal shape. Across five studies with 731 participants navigating a maze with a simulated AI, they argued that people make a strategic cost-benefit choice about whether to engage with an explanation at all. Task difficulty, explanation difficulty and money all shifted how much people over-relied on the AI. Earlier studies that found explanations useless, they suggested, may simply have used explanations that did not make checking the AI any cheaper. Their title made the counterintuitive point: “Explanations Can Reduce Overreliance on AI Systems During Decision-Making”.
Put Cohen's LSAT result beside that framework and a first principle falls out. An explanation earns its place when it lowers the cost of verification. When it raises that cost, or supplies the feeling of verification without the substance, it should be withheld or rebuilt.
Editing the Machine's Mind Feels Like Power
If reading an AI's reasoning can make you overconfident, perhaps the fix is to let users get their hands on it. Interactive reasoning, where people inspect and change a model's chain of thought, has become a fashionable idea in human-computer interaction. A short paper at CHI 2026, the field's flagship conference, held in Barcelona in April, suggests the fashion deserves scrutiny.
Jiwon Moon of the University of Chicago, with Chien-Ming Huang and Ziang Xiao of Johns Hopkins University, published “Understanding the Affordances of Control in AI Reasoning for Human-AI Decision-Making” in the conference's Extended Abstracts, the venue for shorter, often preliminary work. They compared three interfaces in a decision task: no chain of thought, a read-only chain of thought, and an editable one that let users alter the AI's displayed reasoning.
Their abstract captures the gap between how an interface feels and what it does. “Editability significantly increases perceived power, control and satisfaction, but does not improve decision accuracy relative to a no-rationale baseline.” The read-only version was worse: it “increases agreement with the AI and induces inappropriate reliance when the AI is wrong”, reducing accuracy compared with editing and trending below the baseline in which people saw no reasoning at all.
The mechanism is the interesting part. Mediation analyses, the authors report, suggest that editability raises perceived power, which in turn predicts higher confidence and greater over-reliance on incorrect advice, a pattern “consistent with illusion of control.”
The phrase comes from a 1975 paper by the psychologist Ellen Langer in the Journal of Personality and Social Psychology. Across experiments built on games of pure chance, Langer argued that features associated with skill, such as choice, familiarity, involvement and competition, lead people to expect success beyond what the odds justify. Her best-known demonstration, in which people who picked their own lottery ticket asked far more to sell it than people who were handed one, has not aged well: in 2021 Joowon Klusowski, Deborah Small and Joseph Simmons reported in Psychological Science that experiments with more than 10,000 participants found choice alone did not make people think they were more likely to win.
That wrinkle is instructive rather than fatal. Moon, Huang and Xiao measured perceived power directly and linked it to confidence and over-reliance in their own data. But it is a reminder that a vivid label can travel further than the evidence beneath it, which is the subject of this article. Because the CHI paper is an extended abstract, its effect sizes should be treated as provisional. The direction of the result is still a warning to anyone who treats “user control” as an automatic good. Control that is not connected to better outcomes is a feeling, and feelings are what persuasion is made of.
Thirty Years of Leaning on Machines
None of this is new in kind. It is new in fluency.
In 1997, Raja Parasuraman and Victor Riley published “Humans and Automation: Use, Misuse, Disuse, Abuse” in the journal Human Factors. Misuse, in their taxonomy, is over-reliance on automation, producing monitoring failures and decision biases. Disuse is neglect of automation that works, often because it has cried wolf too often. Abuse is automating without regard for the consequences for human performance. All three map onto modern AI assistants, but misuse is the one fluent explanations feed.
In 2004, John Lee and Katrina See gave the field its central goal in the title of their review in the same journal: “Trust in Automation: Designing for Appropriate Reliance”. The key idea is calibration. Trust should match a system's actual trustworthiness, neither overshooting nor undershooting. And it has to work at a fine grain: trusting a system the right amount on average is not enough. You need to trust it more where it is good and less where it is bad.
Medicine has the clearest data on what happens when that fails. A 2012 systematic review in the Journal of the American Medical Informatics Association by Kate Goddard, Abdul Roudsari and Jeremy Wyatt drew on 74 studies of automation bias, which they defined as “the tendency to over-rely on automation”. Pooling four healthcare studies in which decision support systems gave wrong advice, they found the systems increased the risk of an incorrect decision by 26 per cent. The accelerants were familiar: high trust, low self-confidence, workload, complexity, time pressure. Among the design mitigations, they listed attaching updated confidence levels to the system's output, and offering information rather than direct recommendations.
A review published years before large language models went mainstream recommended, in effect, what the RAVEN probability condition did: show people how sure the system is, case by case.
The idea is now law. Article 14 of the European Union's AI Act, on human oversight of high-risk systems, requires that overseers be enabled “to remain aware of the possible tendency of automatically relying or over-relying on the output produced by a high-risk AI system (automation bias)”, particularly where systems provide information or recommendations for decisions taken by people. Those obligations do not bite yet, either: the Digital Omnibus on AI, in force since July 2026, pushed the high-risk deadlines back to December 2027 for standalone systems and August 2028 for AI built into regulated products. The regulation names the problem. It does not specify the interface that solves it. That is the designer's job, and the evidence suggests a fluent paragraph of reasoning is not, by default, the answer.
Explanations Help Most When You Need Them Least
The most cited study on this question predates the language model boom and predicted much of what followed. In 2021, Gagan Bansal and colleagues from the University of Washington and Microsoft Research, among them Besmira Nushi, Ece Kamar, Marco Tulio Ribeiro and Daniel Weld, presented “Does the Whole Exceed its Parts? The Effect of AI Explanations on Complementary Team Performance” at CHI.
Their target was complementary performance: a human-AI team that beats both the human alone and the AI alone. Earlier studies showing that explanations helped had mostly used AI far more accurate than people, so teams improved simply by deferring to a better decision-maker. Bansal's group used AI roughly as accurate as humans, across three tasks (sentiment in beer reviews and book reviews, plus LSAT questions), with 1,626 participants.
Teams did achieve complementary performance, but explanations did not improve on simply showing the AI's confidence. The mechanism was an asymmetry. “Explanations often increased accuracy when the AI system was correct but, worryingly, decreased it when the AI erred, resulting in a minimal net change.” Explanations made people more likely to accept the AI's recommendation whether or not it was right.
Bansal's team tried a fix. Their “adaptive explanation” explained only the top answer when the AI was confident, but laid out the top two alternatives when confidence fell below a threshold, inspired by an efficient assistant that divulges more, “confessing doubts and arguing for alternatives”, only when unsure. It did not significantly improve team performance, though the authors saw suggestive evidence that it nudged agreement in the right direction. Keep it in mind: it is the seed of a better idea.
In 2023, Max Schemmer and colleagues at the Karlsruhe Institute of Technology gave the asymmetry two names. At the Intelligent User Interfaces conference, they proposed measuring “appropriateness of reliance” on separate axes. Relative AI reliance captures how often people switch to correct AI advice after starting with a wrong answer. Relative self-reliance captures how often people keep their own correct answer when the AI is wrong. In their 200-person experiment, explanations raised relative AI reliance from 29.59 to 38.87 per cent. Relative self-reliance did not significantly change.
That is the pattern in miniature. Explanations help people accept the AI when it is right. They do far less to help people resist it when it is wrong. And resistance is the whole point of a human in the loop. If the machine were never wrong, you would not need the person.
Why Fluency Reads as Truth
Large language models sharpen the problem because their explanations are not heatmaps or feature weights. They are prose, and prose is the native format of human persuasion.
In 2025, Mark Steyvers and colleagues at the University of California, Irvine published “What large language models know and what people think they know” in Nature Machine Intelligence. They measured the calibration gap: the difference between how confident people are in a model's answers and how confident the model itself is. Shown default explanations, people overestimated the model's accuracy, and longer explanations raised their confidence even when the extra length did nothing for accuracy. “There's a disconnect between what LLMs know and what people think they know,” Steyvers said in the university's announcement. “We call this the calibration gap.” When the team rewrote explanations so their language reflected the model's internal confidence, that gap narrowed, and people got better at telling right answers from wrong ones.
A year earlier, Sunnie Kim of Princeton University, with Q. Vera Liao, Mihaela Vorvoreanu, Stephanie Ballard and Jennifer Wortman Vaughan of Microsoft, tested something similar. In a pre-registered experiment with 404 participants answering medical questions with a simulated LLM-powered search engine, first-person expressions of uncertainty, along the lines of “I'm not sure, but...”, reduced people's confidence in the system and their agreement with it, and improved their accuracy. Impersonal hedges had weaker effects that did not reach significance. Wording matters enough, the authors concluded, that it needs user testing before deployment.
Back in 2020, Yunfeng Zhang, Q. Vera Liao and Rachel Bellamy of IBM Research found that confidence scores helped people calibrate their trust, while explanations of individual predictions did not do the same job. Their caveat still applies: calibrated trust does not guarantee better decisions unless the human brings knowledge that can compensate for the model's errors. Calibration tells you when to be suspicious. It does not tell you the right answer.
Fluency, in other words, is not a neutral property. Length, confident tone and smooth reasoning all signal reliability without being connected to it. A well-designed system should make those signals honest, or remove them.
Friction Works and Nobody Likes It
If people skim explanations and defer, the obvious response is to make deferral harder. Zana Buçinca, Maja Barbara Malaya and Krzysztof Gajos of Harvard University tested exactly this in “To Trust or to Think: Cognitive Forcing Functions Can Reduce Overreliance on AI in AI-assisted Decision-making”, published in 2021 in the Proceedings of the ACM on Human-Computer Interaction.
Borrowing from research on diagnostic error in medicine, they built three interventions into a task in which 199 participants judged how to cut the carbohydrate content of meals. In the “on demand” condition, the AI's suggestion stayed hidden until people clicked to see it. In “update”, people decided first and could revise after seeing the AI's advice. In “wait”, a message saying the AI was processing the image appeared for 30 seconds before the suggestion arrived.
All three significantly reduced over-reliance compared with simple explainable AI interfaces. None eliminated it: the interventions “reduced, but not yet eliminated, overreliance on the AI”, and the human-AI teams still underperformed the AI alone. Then the twist. When the AI was wrong, “people performed best in conditions that they preferred and trusted the least”, which they also rated most difficult. The interventions also helped people high in “need for cognition”, a measure of how much someone enjoys effortful thinking, more than others, raising the question of who friction actually protects.
This is the commercial problem in one finding. Every metric a product team watches, from satisfaction scores to stated trust, rewards the smooth, confident explanation. The metric that matters, whether people catch the machine's errors, rewards friction. Moon, Huang and Xiao found the same split from the other side. And a 2026 CHI review of reliance research by Muhammad Raees, Vassilis-Javed Khan, Ioanna Lykourentzou and Konstantinos Papangelis made the general point: user engagement is valuable for appropriate reliance, but it comes at a cost.
When to Withhold the Explanation
So when should a designer leave the explanation out? The evidence supports no blanket rule, and the revised Cohen paper is explicit that no single strategy wins everywhere. But it does point to conditions under which a default explanation is more likely to hurt than help.
The first is when the explanation cannot be checked against evidence the user can see. The RAVEN rationale asked people to verify a verbal account of a visual pattern; the LSAT rationale asked them to verify a verbal account of a verbal argument. Where explanation and evidence live in different media, or the evidence is hidden, the explanation tends to function as a confidence signal rather than an argument. Vasconcelos's cost-benefit framing predicts exactly this.
The second is when fluency is decoupled from reliability. A language model can write an equally polished rationale for a right answer and a wrong one, and Steyvers's results show that people read polish and length as accuracy. If a system cannot make the style of its explanation track its actual confidence, the explanation is broadcasting a false signal.
The third is when the user cannot bring independent knowledge. Zhang, Liao and Bellamy's caveat applies: suspicion helps only if the human can act on it. Goddard's review identified time pressure, workload and complexity as amplifiers of automation bias, precisely when people are least able to scrutinise a paragraph of reasoning. In those conditions, a persuasive explanation mostly accelerates deference.
The fourth is before the user has formed a view. Buçinca's update condition and Cohen's multi-stage design both suggest timing matters. An explanation shown before someone has thought for themselves anchors them. Shown afterwards, as a challenge rather than a verdict, it does a different job.
None of this means explanations should vanish. Withholding an explanation from the moment of decision is not the same as withholding it from the record. Engineers debugging a model, auditors checking it and people contesting its verdicts may all need a full account. The question here is narrower: what to put in front of someone in the seconds when they decide whether to accept the machine's answer. The default, an explanation attached to every answer and displayed immediately, is the wrong default for a large class of tasks.
How to Rebuild an Explanation
Withholding is the blunt option. Restructuring is more interesting, and the literature offers several patterns.
Lead with uncertainty rather than reasoning. In Cohen's RAVEN study, the probability display recovered best from errors and was rated clearest by participants, despite explaining nothing. Goddard's review flagged confidence displays more than a decade ago, and Kim's work shows uncertainty can be expressed in natural language, if the phrasing is tested. A number or a well-chosen hedge is a cue to look harder, cheap to read and hard to mistake for an argument.
Make explanations conditional, in the spirit of Bansal's adaptive design. When the model is confident and historically reliable on this kind of case, a short answer may suffice. When it is uncertain, it should do the opposite of what fluent assistants usually do: argue against itself, present the strongest alternative, and show what evidence would change its answer.
Stop recommending and start evaluating. In a 2023 paper at the ACM Conference on Fairness, Accountability and Transparency, titled “Explainable AI is Dead, Long Live Explainable AI! Hypothesis-driven decision support”, Tim Miller, then at the University of Melbourne, argued that recommendations plus explanations undermine human agency and do not match how people reason. He proposed “evaluative AI”, tools that “provide evidence for and against decisions made by people” rather than handing them a decision to accept or reject. The human proposes; the machine stress-tests. There is nothing to be persuaded of, because the machine is not selling an answer.
Sequence the interaction. Ask for the human's judgement first, reveal the AI's view second, and explain only where they disagree. That combines Buçinca's update intervention with adaptive explanation, concentrating scarce attention where it could change the outcome.
Route the cases. Machine learning researchers have long studied “learning to defer”; a 2020 paper at the International Conference on Machine Learning by Hussein Mozannar and David Sontag, for instance, developed methods for training a model that either predicts or hands the decision to a human expert. Cohen's selective-automation benchmark gestures at the same idea, and the authors note that humans can keep final authority under such schemes. Human scepticism is a scarce resource and should be spent where the model is weakest.
A Framework Built Around Distrust
Pull these threads together and a framework for calibrated reliance emerges. Its goal is not understanding but discrimination: helping people tell the machine's good answers from its bad ones, case by case. What follows is a synthesis of the research above, not a standard anyone has yet adopted.
Measure the right thing. Evaluate a system separately on cases where the AI is right and cases where it is wrong, which is the first recommendation in the revised Cohen paper. Schemmer's two axes offer one method; error recovery offers another. Overall accuracy and trust ratings on their own are close to useless, because the Cohen, Bansal, Buçinca and Moon studies all show satisfaction and confidence moving independently of decision quality.
Make every confidence signal honest. If explanations sound equally sure whether the model is right or wrong, their style is lying. Either calibrate the language to the model's real confidence, as Steyvers's team did, or strip out the persuasive styling and show a calibrated number. One caveat: Cohen's RAVEN probabilities were not carefully calibrated, and the authors warn that uncertainty alone can miss errors the model makes confidently. Probability displays are a starting point, not a solution.
Match support to the task's evidence. Where users can verify an explanation against material in front of them, as with the LSAT, rich explanations can pay their way. Where they cannot, prefer uncertainty cues, contrastive alternatives or nothing at all. This is the core lesson of the revised Cohen paper, and a direct rejection of one-size-fits-all explainability.
Protect independent judgement. Elicit the human's view before revealing the machine's wherever time allows, and present explanations as challenges to disagreement rather than justifications for agreement.
Budget friction. Buçinca's results show friction works and people dislike it. Applied everywhere, it wears people down and pushes them back towards blind acceptance. Applied where the model is uncertain, the stakes are high and the human might know better, it earns its cost.
Distrust the feeling of control. Moon, Huang and Xiao's work warns that editing, steering and customising can raise users' sense of power without improving outcomes. Every control affordance should be tested against accuracy on cases where the AI is wrong, not just against satisfaction.
Treat oversight law as a design brief. Article 14 asks that overseers “remain aware” of automation bias. Awareness is not a pop-up warning. It is an interface that makes the machine's fallibility visible at the moment of decision.
The Researchers Who Took Their Own Advice
The revision of the Cohen paper is worth dwelling on. The first version made a vivid, general claim with a memorable name. The second narrowed it, flagged its statistical limits, demoted its most appealing benchmark to a reference point, and concluded that the right answer depends on the task. The authors noticed that their framing was more confident than their evidence, and they recalibrated. The Langer replication story is the same lesson at a fifty-year scale.
That is precisely the behaviour a calibrated-reliance interface tries to produce, and it is hard. Product teams have every commercial reason to keep the fluent, confident explanation, which tests well, demos well and makes users feel smart. The evidence from Bansal in 2021 to Moon in 2026 says that feeling is not the same as being right, and the two can pull in opposite directions.
The explainable AI movement rested on an appealing premise: if people understand why a machine says what it says, they will use it better. The premise is not wrong so much as incomplete. Understanding helps when it gives people something to check. When it gives them only something to believe, it becomes another form of persuasion, and a more effective one than a bare answer, because it looks like reasoning.
The goal, then, is not more explanation or less, but better-aimed explanation: cheap to verify, honest about uncertainty, sequenced so it does not pre-empt human judgement, and most forthcoming when the machine is least sure. Judge it on one question above all: when the model was wrong, did the person notice?
In the RAVEN study, people reading fluent explanations caught roughly one AI error in six. Shown a number instead, they caught more than one in three. Neither is good enough, and the gap between them is statistically fragile. But it points towards where better designs will come from: interfaces built not to win the user's trust, but to earn it one case at a time, and to surrender it gracefully when it has not been earned.
References and Sources
All URLs accessed and verified on 29 October 2026.
- Cohen, Ruth; Feng, Lu; Bloch, Ayala; Kraus, Sarit. “The Persuasion Paradox: When LLM Explanations Fail to Improve Human-AI Team Performance.” arXiv:2604.03237v1, first version, 2026 (superseded). https://arxiv.org/abs/2604.03237v1 (full text: https://arxiv.org/html/2604.03237v1)
- Cohen, Ruth; Feng, Lu; Bloch, Ayala; Kraus, Sarit. “Supporting Calibrated Reliance in Human-AI Collaboration: Different Strategies for Different Tasks.” arXiv:2604.03237v2, revised 18 August 2026. https://arxiv.org/abs/2604.03237 (full text: https://arxiv.org/html/2604.03237v2)
- alphaXiv listing for arXiv:2604.03237, “The Persuasion Paradox: When LLM Explanations Fail to Improve Human-AI Team Performance.” https://www.alphaxiv.org/abs/2604.03237v1
- Moon, Jiwon; Huang, Chien-Ming; Xiao, Ziang. “Understanding the Affordances of Control in AI Reasoning for Human-AI Decision-Making.” In Extended Abstracts of the 2026 CHI Conference on Human Factors in Computing Systems (CHI EA '26), Barcelona, 13 to 17 April 2026, pp. 1-9. ACM. DOI: 10.1145/3772363.3798555. https://doi.org/10.1145/3772363.3798555
- Semantic Scholar record and abstract for Moon, Huang and Xiao (2026), Corpus ID 287443795. https://api.semanticscholar.org/graph/v1/paper/DOI:10.1145/3772363.3798555?fields=title,abstract,authors,venue,year
- Langer, Ellen J. “The illusion of control.” Journal of Personality and Social Psychology, 32(2), 311-328, August 1975. DOI: 10.1037/0022-3514.32.2.311. https://doi.org/10.1037/0022-3514.32.2.311
- Klusowski, Joowon; Small, Deborah A.; Simmons, Joseph P. “Does Choice Cause an Illusion of Control?” Psychological Science, 32(2), 159-172, 2021. DOI: 10.1177/0956797620958009. https://faculty.wharton.upenn.edu/wp-content/uploads/2016/11/36-Klusowski-Small-Simmons-2021.pdf
- Yale School of Management, Yale Insights. “Does Having Choice Provide an Illusion of Control?” https://insights.som.yale.edu/insights/does-having-choice-provide-an-illusion-of-control
- Bansal, Gagan; Wu, Tongshuang; Zhou, Joyce; Fok, Raymond; Nushi, Besmira; Kamar, Ece; Ribeiro, Marco Tulio; Weld, Daniel S. “Does the Whole Exceed its Parts? The Effect of AI Explanations on Complementary Team Performance.” In Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems, Yokohama, May 2021, pp. 1-16. ACM. DOI: 10.1145/3411764.3445717. arXiv:2006.14779. https://arxiv.org/abs/2006.14779
- Buçinca, Zana; Malaya, Maja Barbara; Gajos, Krzysztof Z. “To Trust or to Think: Cognitive Forcing Functions Can Reduce Overreliance on AI in AI-assisted Decision-making.” Proceedings of the ACM on Human-Computer Interaction, 5(CSCW1), Article 188, pp. 1-21, April 2021. DOI: 10.1145/3449287. https://kgajos.seas.harvard.edu/papers/bucinca21trust.pdf
- Vasconcelos, Helena; Jörke, Matthew; Grunde-McLaughlin, Madeleine; Gerstenberg, Tobias; Bernstein, Michael S.; Krishna, Ranjay. “Explanations Can Reduce Overreliance on AI Systems During Decision-Making.” Proceedings of the ACM on Human-Computer Interaction, 7(CSCW1), pp. 1-38, April 2023. DOI: 10.1145/3579605. arXiv:2212.06823. https://arxiv.org/abs/2212.06823
- Schemmer, Max; Kühl, Niklas; Benz, Carina; Bartos, Andrea; Satzger, Gerhard. “Appropriate Reliance on AI Advice: Conceptualization and the Effect of Explanations.” In Proceedings of the 28th International Conference on Intelligent User Interfaces (IUI '23), Sydney, March 2023, pp. 410-422. ACM. DOI: 10.1145/3581641.3584066. arXiv:2302.02187. https://arxiv.org/abs/2302.02187
- Zhang, Yunfeng; Liao, Q. Vera; Bellamy, Rachel K. E. “Effect of Confidence and Explanation on Accuracy and Trust Calibration in AI-Assisted Decision Making.” In Proceedings of the 2020 Conference on Fairness, Accountability, and Transparency (FAT* '20), January 2020, pp. 295-305. ACM. DOI: 10.1145/3351095.3372852. arXiv:2001.02114. https://arxiv.org/abs/2001.02114
- Kim, Sunnie S. Y.; Liao, Q. Vera; Vorvoreanu, Mihaela; Ballard, Stephanie; Vaughan, Jennifer Wortman. “'I'm Not Sure, But...': Examining the Impact of Large Language Models' Uncertainty Expression on User Reliance and Trust.” In The 2024 ACM Conference on Fairness, Accountability, and Transparency (FAccT '24), June 2024, pp. 822-835. DOI: 10.1145/3630106.3658941. arXiv:2405.00623. https://arxiv.org/abs/2405.00623
- Steyvers, Mark; Tejeda, Heliodoro; Kumar, Aakriti; Belem, Catarina; Karny, Sheer; Hu, Xinyue; Mayer, Lukas W.; Smyth, Padhraic. “What large language models know and what people think they know.” Nature Machine Intelligence, 7(2), 221-231, 2025. DOI: 10.1038/s42256-024-00976-7. https://www.nature.com/articles/s42256-024-00976-7 (preprint: https://arxiv.org/abs/2401.13835)
- University of California, Irvine, School of Social Sciences. “UC Irvine study finds mismatch between human perception and reliability of AI-assisted language tools.” 22 January 2025. https://www.socsci.uci.edu/newsevents/news/2025/2025-01-22-steyvers-uci-study-finds-mismatch-between-human-perception-and-reliability-of-ai-assisted-language-tools.php
- Parasuraman, Raja; Riley, Victor. “Humans and Automation: Use, Misuse, Disuse, Abuse.” Human Factors, 39(2), 230-253, June 1997. DOI: 10.1518/001872097778543886. https://journals.sagepub.com/doi/10.1518/001872097778543886
- Lee, John D.; See, Katrina A. “Trust in Automation: Designing for Appropriate Reliance.” Human Factors, 46(1), 50-80, 2004. DOI: 10.1518/hfes.46.1.50_30392. https://pubmed.ncbi.nlm.nih.gov/15151155/
- Goddard, Kate; Roudsari, Abdul; Wyatt, Jeremy C. “Automation bias: a systematic review of frequency, effect mediators, and mitigators.” Journal of the American Medical Informatics Association, 19(1), 121-127, January 2012. DOI: 10.1136/amiajnl-2011-000089. https://pmc.ncbi.nlm.nih.gov/articles/PMC3240751/
- Miller, Tim. “Explainable AI is Dead, Long Live Explainable AI! Hypothesis-driven decision support.” In Proceedings of the 2023 ACM Conference on Fairness, Accountability, and Transparency (FAccT '23), June 2023, pp. 333-342. DOI: 10.1145/3593013.3594001. arXiv:2302.12389. https://arxiv.org/abs/2302.12389
- Mozannar, Hussein; Sontag, David. “Consistent Estimators for Learning to Defer to an Expert.” In Proceedings of the 37th International Conference on Machine Learning (ICML 2020), PMLR 119, pp. 7076-7087. arXiv:2006.01862. https://arxiv.org/abs/2006.01862
- Raees, Muhammad; Khan, Vassilis-Javed; Lykourentzou, Ioanna; Papangelis, Konstantinos. “Do People Appropriately Rely on AI-Advice? An Analytical Review of HCI Research on Human-AI Decision-Making.” In Proceedings of the 2026 CHI Conference on Human Factors in Computing Systems, Barcelona, April 2026, Article 805. ACM. DOI: 10.1145/3772318.3791467. https://research-portal.uu.nl/en/publications/do-people-appropriately-rely-on-ai-advice-an-analytical-review-of/
- Regulation (EU) 2024/1689 of the European Parliament and of the Council of 13 June 2024 (Artificial Intelligence Act), Article 14 (Human oversight). Official Journal L, 12 July 2024. https://ai-act-service-desk.ec.europa.eu/en/ai-act/article-14 ; https://artificialintelligenceact.eu/article/14/
- Regulation (EU) 2026/1744 of the European Parliament and of the Council of 8 July 2026 amending Regulations (EU) 2024/1689, (EU) 2018/1139 and (EU) 2023/1230 as regards the simplification of the implementation of harmonised rules on artificial intelligence (Digital Omnibus on AI). Official Journal L, 24 July 2026; in force 27 July 2026. https://eur-lex.europa.eu/eli/reg/2026/1744/oj
Tim Green UK-based Systems Theorist & Independent Technology Writer
Tim explores the intersections of artificial intelligence, decentralised cognition, and posthuman ethics. His work, published at smarterarticles.co.uk, challenges dominant narratives of technological progress while proposing interdisciplinary frameworks for collective intelligence and digital stewardship.
His writing has been featured on Ground News and shared by independent researchers across both academic and technological communities.
ORCID: 0009-0002-0156-9795 Email: tim@smarterarticles.co.uk
Listen to the free weekly SmarterArticles Podcast
Why I built a hockey romance books site
from Sparks Apps
One of the side projects I run next to readalikes.ai is a hockey romance books site, hockeyromancebooks.com. It's one of several exact-match domains I'm building, each one focused on a single, very specific search.
The genre is bigger than most people think. The site now lists 4,092 books, sorted by trope, heat level and pairing.
The search numbers
This is why the niche caught my eye. According to US keyword data, “hockey romance books” averages about 27,100 searches a month, and “hockey romance novels” gets about the same.
The growth is the wild part:
- Early 2019: about 390 searches a month.
- January 2022: about 1,900.
- January 2025: about 12,100.
- December 2025: a peak of 135,000 in a single month.
It has cooled since, landing around 6,600 in August 2026. That's still roughly 17 times where it was in 2019. Keyword difficulty is listed at 0, which is rare for a search that size.
How it works
Readers rarely search for “a good book.” They search for the exact thing they want. So the site is built around tropes:
- Enemies to lovers for rival players and teams who can't stand each other.
- Grumpy sunshine for the moody captain and the person who melts him.
- Fake dating for the “it's just for the cameras” setup.
- The full trope list covers everything else, from figure skaters to second chances.
How it ties into readalikes
Readalikes.ai is the broad version: find your next book with AI, picks from well-known people and community recommendations. The niche sites go deep on one corner of reading. Same goal, different entry points. If someone finishes a hockey romance and wants something outside the genre, readalikes.ai is the next stop.
Why exact-match domains
My read: a site named after the exact search has a clear focus, and that helps both readers and search engines know what it's about. The catch is that it has to be genuinely useful, not a thin page with a keyword in the URL. So each one gets real depth on its topic.
More of these are coming. I'll share what works and what doesn't.
Building the readalikes.ai mobile app
from Sparks Apps
I'm building a mobile app for readalikes.ai. The goal is simple: make it the best place to find your next book.
Most book apps lean on star ratings. Readalikes skips those and mixes three things instead.
- AI search. Name a book you loved and the AI book recommender finds similar ones, with filters to narrow it down. You can import your Goodreads library too.
- Influential people. Book picks from well-known people, pulled from celebrity podcast episodes, so you can read what the people you follow are reading.
- Community. Everyone who signs up shares one book they'd recommend. One pick each, no ratings. You can browse them on the community page.
How I'm growing it
SEO is a big part of the plan. I publish “books like” lists for popular titles, so people searching for their next read land on the site. A few examples:
- Books like A Gentleman in Moscow
- Books like Shoe Dog
- Books like The Covenant of Water
- Books like Can't Hurt Me
- Books like Yellowface
What's next
The website just launched. The app is next, so the same picks fit in your pocket when you're standing in a bookstore wondering what to grab. More updates soon as it comes together.
This is my main focus right now. But I have almost 20 other projects on the go right now. The plan is to build a powerful system using Grokbot to grow these. Stay tuned 👀